Moonshot veroeffentlicht Kimi K3.1 Pro in der API, Open Weights angekündigt
Moonshot hat Kimi K3.1 Pro in der Kimi API verfuegbar gemacht, die Modellgewichte sollen bis November 2026 offengelegt werden. Neben einer Highspeed-Variante, die zwei- bis dreimal schneller arbeitet und doppelt so viel kostet, gibt es Rabatte auf Input-Token-Cache-Treffer.
Vorstellung von Kimi K3.1 Pro (via) Kimi K3.1 Pro ist heute über die Kimi API verfügbar. Es handelt sich noch nicht um offene Modellgewichte, doch Moonshot verspricht: „Die vollständigen Modellgewichte werden bis zum 4. November 2026 veröffentlicht.“
Zudem wird eine „Highspeed“-Variante angeboten, die zwei- bis dreimal schneller ist und den doppelten Preis kostet (mit Ausnahme von Cache-Treffern bei Eingabetokens, die zum selben Preis abgerechnet werden).
Die Preise in US-Dollar liegen bei 2,00 Dollar pro Million Tokens für die Eingabe und 10 Dollar pro Million für die Ausgabe, also auf dem Niveau von GPT-6.1 Sol und halb so teuer wie Claude Opus 5.5.
Moonshots eigene Benchmarks zeigen Kimi in etwa auf Augenhöhe mit Opus 5.5 und GPT-6 Astra. Auf einigen Benchmarks liegt es vorn, auf anderen knapp dahinter.
Artificial Analysis bewertete Kimi mit 55 Punkten und reihte es damit vor Claude Fable 5.1, GPT-6 Astra und Gemini 4 Argon (alle 53) ein, nur Claude Opus 5.5 (58) liegt noch darüber.
Das ist das erste Mal, dass ein (bald) offenes Modell im Vergleich zur Frontier solch hohe Werte erreicht.
Ich habe es über die Moonshot API mit dem Befehl llm openai endpoint ausprobiert, den ich im August in LLM 0.32 ergänzt hatte:
llm openai endpoint \ https://api.moonshot.ai/v1 \ --key kimi \ -m kimi-k3.1-pro \ "Generate an SVG of a pelican riding a bicycle" \ --responses \ -o reasoning_effort low \ > kimi-k3.1-pro-pelican-low.stdout.txt \ 2> kimi-k3.1-pro-pelican-low.stderr.txt Der Befehl llm openai endpoint kann Prompts gegen jeden OpenAI-kompatiblen Endpoint ausführen, protokolliert die Ergebnisse aber nicht. Daher die zusätzlichen Optionen, um stdout und stderr (den Reasoning Trace) zu speichern.
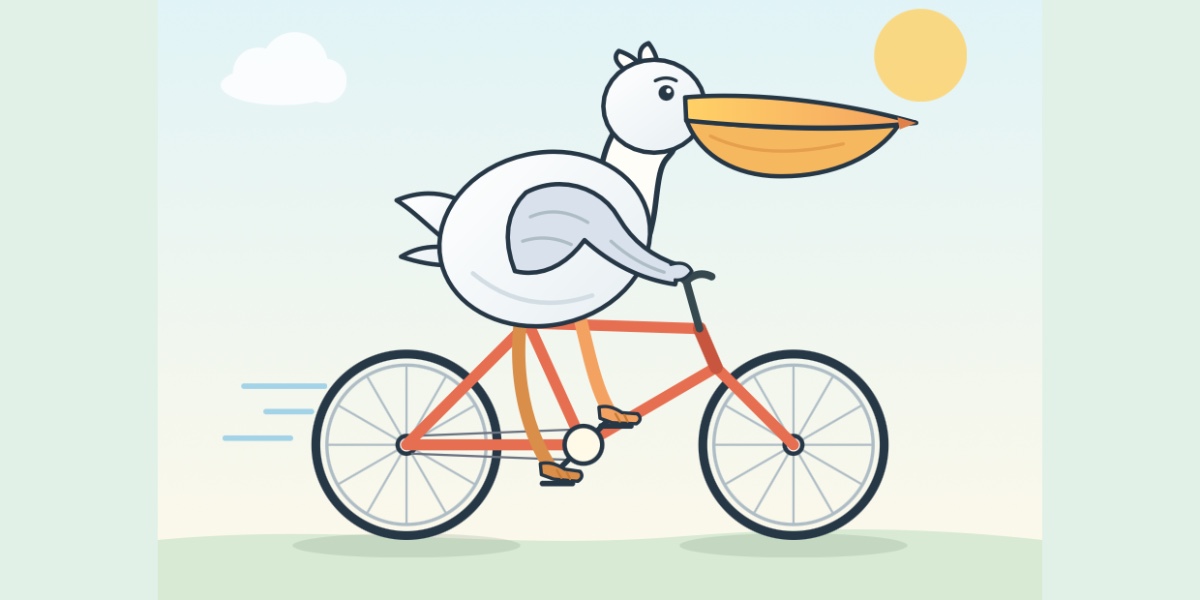
Hier sind die Pelikane, die ich für Kimi K3.1 Pro auf den drei unterstützten Reasoning-Stufen erhalten habe, also low, medium und max. Dies ist max:
Zum Vergleich habe ich frische Pelikane für Kimi K3 auf diesen drei Reasoning-Stufen generieren lassen.
Dies ist ein Link-Beitrag von Simon Willison, veröffentlicht am 23. Oktober 2026.
Sponsore mich mit 10 Dollar im Monat und erhalte einen kuratierten E-Mail-Überblick über die wichtigsten LLM-Entwicklungen des Monats.
Automatisch übersetzt. Das Original auf Englisch ist unten aufklappbar.
Original (Englisch) anzeigen
Introducing Kimi K3.1 Pro ( via ) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".
They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).
The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.
Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.
I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:
llm openai endpoint \ https://api.moonshot.ai/v1 \ --key kimi \ -m kimi-k3.1-pro \ "Generate an SVG of a pelican riding a bicycle" \ --responses \ -o reasoning_effort low \ > kimi-k3.1-pro-pelican-low.stdout.txt \ 2> kimi-k3.1-pro-pelican-low.stderr.txt llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).
Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:
For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.
This is a link post by Simon Willison, posted on 23rd October 2026.
Sponsor me for $10/month and get a curated email digest of the month's most important LLM developments.