More Performance From Every Byte: How Full-Stack Codesign Solves AI’s Memory Challenge
Larger models, longer contexts and agentic applications are increasing GPU memory pressure while supply tightens and prices rise — a trend expected to continue through the near term. NVIDIA works closely with memory partners to rapidly adopt the latest memory technologies. NVIDIA was first to adopt
Larger models, longer contexts and agentic applications are increasing GPU memory pressure while supply tightens and prices rise — a trend expected to continue through the near term.
NVIDIA works closely with memory partners to rapidly adopt the latest memory technologies. NVIDIA was first to adopt HBM3e and HBM4 technologies into an accelerated computing stack.
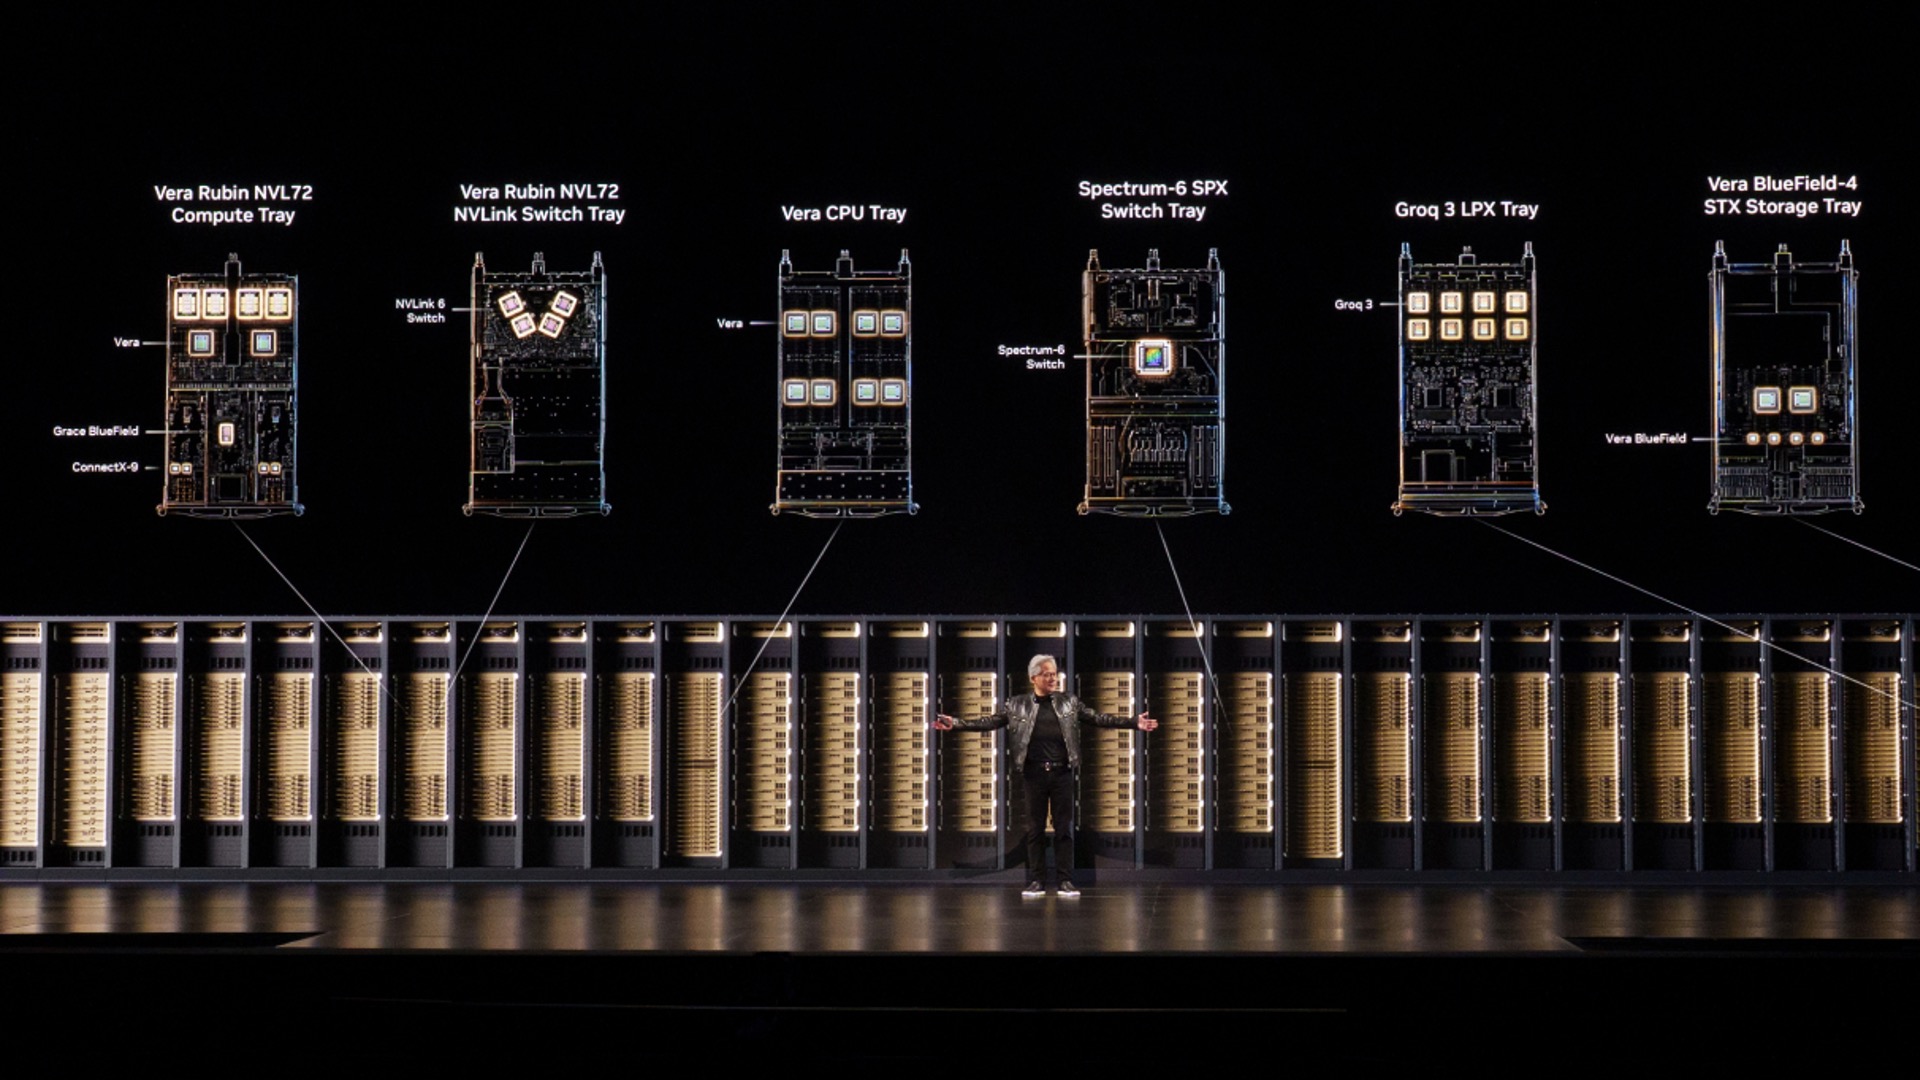
But the approach isn’t to simply pack more memory onto the GPU. It’s full-stack codesign. NVIDIA intentionally designs GPUs, CPUs, networking, storage and software together to get more useful work out of memory at every layer of the AI factory.
That matters because an AI factory runs on a memory and storage hierarchy. GPU high-bandwidth memory (HBM) is the fastest, most expensive and most contested tier — with model weights and KV cache competing for limited capacity. Below it sit CPU memory, local SSDs and shared storage, each trading speed for more capacity at a lower cost per bit.
How much useful work a byte does depends on how well the whole hierarchy is used: shrinking what must be stored, placing it on the right tier and bringing it back to the GPU before it’s needed.
Byte for byte, NVIDIA makes the most efficient use of memory at every layer — and the results show it. From NVIDIA Blackwell Ultra to the Vera Rubin platform, HBM capacity per GPU rose roughly 3%, while agentic throughput per dollar rose by up to 30x on SemiAnalysis AgentX.
Frontier models now have trillions of parameters — the values that hold what an AI model learned in training.
KV cache, which holds the context the model needs to understand each active request without reprocessing the same information, is also expanding. Agentic trajectories carry prior context across repeated model and tool calls, in some cases processing up to 3 million tokens, so each request’s working memory grows over time.
Retrieval-augmented generation (RAG) adds relevant enterprise information to prompts, creating even more context to process and retain.
During inference, HBM primarily holds both model parameters and KV cache. The result: greater pressure on HBM.
Adding more HBM capacity per GPU is the obvious response to that pressure, but capacity delivers only what bandwidth can move.
Think of HBM as a warehouse and memory bandwidth as its loading docks. A larger warehouse holds more inventory, but the docks set how much can move in and out at a time. Once the docks are at capacity, moving more inventory takes longer and slows response times. If delays exceed the required service level, the added space can’t be used effectively, even as it adds cost and draws power.
That’s also why no operation keeps all its inventory in the closest, fastest space. What’s in motion stays near the line. What’s waiting moves to a larger, cheaper space nearby and returns before it’s needed.
More HBM can hold more KV cache and support more concurrent users. Every added user shares the same compute and memory bandwidth. But when each user expects fast responses, eventually memory bandwidth is unable to supply data as fast as compute can use it: a limit engineers call the memory wall.
Past that point, extra HBM capacity can’t be put to work, yet it still adds costs and draws power. The data still needs a place to live, but not all of it needs the fastest, most expensive tier. This is why an AI factory manages data across a memory and storage hierarchy.
NVIDIA’s full-stack codesign makes every byte of HBM count by relieving pressure from model weights, KV cache and RAG data. It does this with techniques that each target a different source of inefficiency:
Shrink model weights and distribute them across the NVL72 domain.
Shrink KV-cache and offload inactive context to lower-cost storage tiers.
Compact RAG embeddings and keeping the index outside HBM.
The result is less HBM used for model weights, less HBM tied up by idle context and more of it available to serve concurrent users.
Across successive NVIDIA platform generations, tokens per second per dollar has risen far faster than HBM capacity.
On the SemiAnalysis AgentX DeepSeek V4 Pro workload, NVIDIA GB300 NVL72 delivers up to 10x higher throughput per dollar than NVIDIA H200 platform at 100 tokens per second per user, with HBM capacity per GPU roughly doubling. At 125 tokens per second per user, Vera Rubin NVL72 delivers up to 30x higher throughput per dollar than GB300 NVL72, with HBM capacity per GPU up about 3%.
For AI factory operators, the metric that matters is how many useful tokens the factory can deliver within its power budget while meeting user response-time needs. More tokens per second per watt means more work and revenue from the same power, and a lower cost for every token. NVIDIA’s full-stack codesign lowers token costs by increasing the useful work every byte of memory delivers.
Learn more in the video explainer and technical deep dive on how NVIDIA full-stack codesign reduces inference memory pressure.